LLM: OpenRouter vs OmniRoute Gateways
12 October 2026, Carlos Pena
TL;DR: Use OpenRouter for the widest catalog and features like its auto router. Use OmniRoute (Cheaper Inference) when you already know which models you want and just want to pay less for them.
All of them give you one OpenAI-compatible endpoint in front of many LLM providers.
- OpenRouter - a hosted marketplace. You buy credits, it proxies to the providers at list price plus a fee.
- OmniRoute - comes in two flavors:
- Self-hosted - open source (MIT), runs on your machine and routes between your own accounts, free tiers and subscriptions.
- Hosted - sold as Cheaper Inference (platform.cheaperinference.com). One key, it routes each request to discounted sources and charges below list price.
The naming is confusing: same project, but the hosted one has its own brand, domain, keys (ci_live_...) and docs, and the two do not share all features. The code examples below use the hosted one.
Quick comparison
| OpenRouter | OmniRoute (self-hosted) | OmniRoute (Cheaper Inference) | |
|---|---|---|---|
| Runs on | Their servers | Your machine (npm, Docker, desktop) | Their servers |
| Endpoint | https://openrouter.ai/api/v1 |
http://localhost:20128/v1 |
https://api.cheaperinference.com/v1 |
| Billing | Prepaid credits, fee on top | Free; you pay each provider directly | Prepaid wallet (from $5) |
| Price | List price | Whatever your accounts cost; free tiers first | Below list, never above |
| Keys | One OpenRouter key | Your own key/login per provider | One ci_live_ key |
| Fallback | Across providers, plus a models list you choose |
Across your providers, models, subscriptions and free tiers | Automatic across sources of the same model |
| Routing knob | provider.sort (price, throughput, latency) |
auto/* aliases and combos (19 strategies) |
ranking (discount, speed, balance) |
| Privacy | zdr, data_collection |
Gateway is local; data goes only to providers you connect | zdr, or ZDR for the whole account |
| Caching | Provider prompt caching | Provider prompt caching + semantic cache | Provider prompt caching + exact-response cache |
| Claude Code | No Anthropic endpoint | Supported | Yes (/v1/messages) |
| Extras | Auto router, web search | Token compression, MCP server, local dashboard | Token-saving techniques, A/B experiments, spend reports |
| Ops | None | You host, update and secure it | None |
| Best for | Widest model catalog | Squeezing free tiers and subscriptions you already have | Same models, smaller bill |
OmniRoute
Change the base_url and the key. The rest is the standard OpenAI SDK:
# uv add openai
import os
from openai import OpenAI

client = OpenAI(
    api_key=os.environ["CHEAPER_INFERENCE_API_KEY"],
    base_url="https://api.cheaperinference.com/v1",
)

response = client.chat.completions.create(
    model="aion-3.0-mini",
    messages=[{"role": "user", "content": "Hello!"}],
)
print(response.choices[0].message.content)
Hello! How can I help you today? Whether you have a question, need assistance with something, or just want to chat, I’m here for you.
What comes back
Printing the whole response object shows the extras. This one used model="claude-sonnet-4.5":
Out[3]: ChatCompletion(
    id="msg_011Cfy8mE8AdvzjjVqcKDc8Y",
    choices=[
        Choice(
            finish_reason="stop", index=0, logprobs=None,
            message=ChatCompletionMessage(
                content="Hello! How can I help you today?",
                refusal=None, role="assistant", annotations=None, audio=None, function_call=None, tool_calls=None,
                reasoning_content='The user is greeting me with "Hello!" This is a simple, friendly greeting. I should respond in a warm and welcoming manner.',
                reasoning_details=[
                    {
                        "type": "reasoning.text",
                        "format": "anthropic-claude-v1",
                        "index": 0,
                        "text": 'The user is greeting me with "Hello!" This is a simple, friendly greeting. I should respond in a warm and welcoming manner.',
                        "signature": "...",
                    }
                ],
            ),
        )
    ],
    created=1791844230,
    model="claude-sonnet-4.5",
    object="chat.completion",
    metadata=None, moderation=None, service_tier=None, system_fingerprint=None,
    usage=CompletionUsage(
        completion_tokens=48, prompt_tokens=38, total_tokens=86, completion_tokens_details=None,
        prompt_tokens_details=PromptTokensDetails(
            audio_tokens=None, cache_write_tokens=None, cached_tokens=0, image_tokens=None, text_tokens=None,
        ),
        cost=0.000542,
        cost_details={"upstream_inference_cost": 0.000542},
    ),
    cheaper_inference={
        "request_id": "6dc36a2c-92f0-42ff-b2a1-de64f7f67274",
        "billing": {
            "status": "settled",
            "billed_cost_usd": "0.000542",
            "currency": "USD",
            "zero_data_retention": False,
            "effective_discount_percent": 35.01199040767386,
        },
    },
)
usage.cost- what you actually paid for this call, in USD.cheaper_inference.billing.effective_discount_percent- how far below list price it was (35% here).cheaper_inference.request_id- the ID to look the call up later or attach feedback to.reasoning_content- Claude’s thinking summary, when the model thinks.
Failed requests are not charged; the wallet is debited only after a request completes.
Routing parameters
Three non-OpenAI fields go in extra_body. The gateway reads them and strips them before forwarding:
response = client.chat.completions.create(
    model="claude-sonnet-4.5",
    messages=[{"role": "user", "content": "Hello!"}],
    max_tokens=1024,
    extra_body={
        "ranking": "speed",  # "discount" | "speed" | "balance" (default)
        "min_discount_percent": 10,  # only sources at least 10% below list; Error code: 503 min_discount_unavailable
        "zdr": True,  # zero data retention providers only
    },
)
There is no field to pick a fallback model. If a source fails before output starts, the gateway retries the same model on the next source, and you are still never charged above list price.
Caching
Two different caches.
Prompt caching (the provider’s). OpenAI, DeepSeek and Gemini cache long prompts on their own. For Claude you mark what to cache with cache_control, or let the gateway add the markers with a header:
response = client.chat.completions.create(
    model="claude-sonnet-4.5",
    messages=[
        {
            "role": "system",
            "content": [
                {
                    "type": "text",
                    "text": LONG_PRODUCT_CATALOG,
                    "cache_control": {"type": "ephemeral"},
                }
            ],
        },
        {"role": "user", "content": "Which items are ...?"},
    ],
    max_tokens=1024,
    extra_headers={
        "x-ci-prompt-cache": "on",  # on | off | passthrough (default); "on" may still be in preview
        "x-ci-prompt-cache-session": "chat-42",  # keep a conversation on the same source
    },
)
print(response.usage.prompt_tokens_details.cached_tokens)  # > 0 on a cache hit
Cache reads cost about 10% of the normal input price. The session header matters because a cache only lives on the provider that wrote it. ZDR turns prompt caching off.
Exact-response cache (the gateway’s). An identical, deterministic request can be answered with a stored reply, without calling a provider. It is an optional technique (id exact-cache) and off by default, so every call is a miss until you enable it, in the dashboard under Techniques or through the API (key needs the account:write scope):
import requests

BASE = "https://api.cheaperinference.com/v1"
HEADERS = {"Authorization": f"Bearer {os.environ['CHEAPER_INFERENCE_API_KEY']}"}

requests.get(
    f"{BASE}/techniques", headers=HEADERS
).json()  # what exists, what is enabled
requests.patch(
    f"{BASE}/techniques/exact-cache", headers=HEADERS, json={"enabled": True}
)
Then send the same request twice, with temperature=0. The first call fills the cache, the second should be a hit:
for _ in range(2):
    raw = client.chat.completions.with_raw_response.create(
        model="aion-3.0-mini",
        messages=[{"role": "user", "content": "Hello!"}],
        temperature=0,  # Necessary
    )
    print(raw.headers.get("x-ci-cache"))  # "miss", then "hit"
    print(raw.headers.get("x-ci-saved-usd"))  # savings on this call
response = raw.parse()
# x-ci-cache miss
# x-ci-techniques
# x-ci-warning None
# x-ci-request-id 3767634b-8a1e-458b-a878-3505af790322

# x-ci-cache hit
# x-ci-techniques exact-cache
# x-ci-warning None
# x-ci-request-id 4ac902eb-49ac-4037-aed9-c65e742f5627
Reasoning
Claude thinking through Chat Completions uses the portable reasoning_effort (none to max). Leave room in max_tokens, since thinking is billed as output:
response = client.chat.completions.create(
    model="claude-sonnet-4.5",
    messages=[{"role": "user", "content": "Plan a 3-day trip to Recife."}],
    reasoning_effort="high",
    max_tokens=8192,
)
print(response.choices[0].message.reasoning_content)
Account endpoints
Same key (with the right scope), same base URL:
import requests

BASE = "https://api.cheaperinference.com/v1"
HEADERS = {"Authorization": f"Bearer {os.environ['CHEAPER_INFERENCE_API_KEY']}"}

requests.get(
    f"{BASE}/models", headers=HEADERS, params={"zdr": "true"}
).json()  # catalog + prices
requests.get(f"{BASE}/account/balance", headers=HEADERS).json()  # needs account:read
requests.get(f"{BASE}/usage/daily", headers=HEADERS).json()  # spend, cache hit %
Keys can be restricted by model, IP range, rate, concurrency and monthly spend, which is handy for giving a key to a side project.
Claude Code
There is also an Anthropic-compatible endpoint, so Claude Code can run through it. No /v1 at the end, the client adds it:
export ANTHROPIC_BASE_URL="https://api.cheaperinference.com"
export ANTHROPIC_AUTH_TOKEN="$CHEAPER_INFERENCE_API_KEY"
claude
OpenRouter
OpenRouter has its own Python SDK (the OpenAI SDK with base_url="https://openrouter.ai/api/v1" also works):
# uv add openrouter
# export OPENROUTER_API_KEY="sk-or-v1-..."
import os
from openrouter import OpenRouter

with OpenRouter(api_key=os.getenv("OPENROUTER_API_KEY", "")) as client:
    response = client.chat.send(
        model="openai/gpt-oss-20b",
        messages=[{"role": "user", "content": "Good morning!"}],
    )
    print(response.choices[0].message.content)
Model IDs are provider/model. A :free suffix marks a free variant (rate limited). To find the exact string for model=, list them:
with OpenRouter(api_key=os.getenv("OPENROUTER_API_KEY", "")) as client:
    for model in client.models.list().data:
        if model.id.endswith(":free"):
            print(f"{model.name} -> {model.id}")
Apodex: Apodex 1.1 Mini (free) -> apodex/apodex-1.1-mini:free // works
Dots Studio: Dots3-Note Preview (free) -> dots-studio/dots-3-note-preview:free
LiquidAI: LFM2.5-2.6B (free) -> liquid/lfm-2.5-2.6b:free
NVIDIA: Nemotron 3.5 Lightning (free) -> nvidia/nemotron-3.5-lightning:free
Thinking Machines: Inkling Small (free) -> thinkingmachines/inkling-small:free
Poolside: Laguna S 2.1 (free) -> poolside/laguna-s-2.1:free
Thinking Machines: Inkling (free) -> thinkingmachines/inkling:free
Poolside: Laguna XS 2.1 (free) -> poolside/laguna-xs-2.1:free
Cohere: North Mini Code (free) -> cohere/north-mini-code:free
NVIDIA: Nemotron 3.5 Content Safety (free) -> nvidia/nemotron-3.5-content-safety:free
NVIDIA: Nemotron 3 Ultra (free) -> nvidia/nemotron-3-ultra-550b-a55b:free
NVIDIA: Nemotron 3 Nano Omni (free) -> nvidia/nemotron-3-nano-omni-30b-a3b-reasoning:free
Google: Gemma 4 26B A4B  (free) -> google/gemma-4-26b-a4b-it:free // 2026-10-12 TooManyRequestsResponseError
Google: Gemma 4 31B (free) -> google/gemma-4-31b-it:free
NVIDIA: Nemotron 3 Super (free) -> nvidia/nemotron-3-super-120b-a12b:free
Jev Router: let Jev pick the model
Jev is TypeSafe’s decision model: it does not write text, it answers typed questions (yes/no, score, choice) with probabilities. OpenRouter offers it in two ways. The first is typesafe/jev-router, a chat model where Jev makes one hidden decision per request:
- Jev reads the prompt and picks the model and reasoning effort.
- That model writes the answer.
with OpenRouter(api_key=os.getenv("OPENROUTER_API_KEY", "")) as client:
    response = client.chat.send(
        model="typesafe/jev-router",
        messages=[{"role": "user", "content": "Good morning!"}],
    )
    print(response.model)  # which model Jev picked
    print(response.choices[0].message.content)
openai/gpt-6-luna
Good morning! How can I help you today?
You pay the price of the model Jev picked (the router is listed at -1, meaning variable), so it is not free. Note it chose a strong model for a simple greeting; check the Activity page before routing lots of trivial traffic through it.
Here Jev’s own answer only shows up indirectly, in response.model.
Jev decisions: ask Jev directly
The second way calls Jev itself, through a separate (alpha) decisions endpoint instead of chat. You send a state and typed questions, and get probabilities back instead of text:
noul- yes/no, returns the probability of “true”.choice- pick one option, returns a probability per option.score- position on an ordered rubric, returns the expected score and a probability per level.
import os

import requests

response = requests.post(
    "https://openrouter.ai/api/alpha/decisions",
    headers={
        "Authorization": f"Bearer {os.environ['OPENROUTER_API_KEY']}",
        "Content-Type": "application/json",
    },
    json={
        "model": "typesafe/jev-1.13",
        "state": {
            "customer_tier": "enterprise",
            "ticket": "My checkout page shows a blank screen after I click Pay. I have tried two browsers.",
        },
        "questions": {
            "is_bug": {
                "type": "noul",
                "instructions": "Is the customer reporting a software defect?",
                "criteria": {
                    "true": "The customer describes broken or unexpected product behavior.",
                    "false": "The customer is asking a question or requesting a feature.",
                },
            },
            "team": {
                "type": "choice",
                "instructions": "Which team should own this ticket?",
                "criteria": {
                    "payments": "Checkout, billing, or payment processing issues.",
                    "frontend": "Rendering, layout, or browser compatibility issues.",
                    "account": "Login, permissions, or profile issues.",
                },
            },
            "urgency": {
                "type": "score",
                "instructions": "How urgent is this ticket?",
                "criteria": [
                    "Can wait for the next release",
                    "Should be fixed this week",
                    "Blocking revenue right now",
                ],
            },
        },
    },
)

print(response.json())
{'model': 'typesafe/jev-1.13-20260917',
 'answers': {'is_bug': {'type': 'noul', 'noul': 0.96},
  'team': {'type': 'choice',
   'choice': 'payments',
   'probabilities': {'payments': 0.8, 'frontend': 0.2, 'account': 0},
   'confidence': 0.7},
  'urgency': {'type': 'score',
   'score': 1.99,
   'legend': {'0': 'Can wait for the next release',
    '1': 'Should be fixed this week',
    '2': 'Blocking revenue right now'},
   'probabilities': {'0': 0, '1': 0.01, '2': 0.99},
   'confidence': 0.98}},
 'usage': {'input_tokens': 476, 'output_tokens': 70, 'cost': 1.9992e-05},
 'id': 'gen-dec-1791848249-g8VemRkIFVRDfTjSIm3i',
 'provider': 'TypeSafe'}
Three decisions for about $0.00002, and each answer is a dict key, not text to parse: answers["team"]["choice"] is "payments". The probabilities are useful as thresholds, for example auto-route only when confidence is high and send the rest to a human. The endpoint is alpha, so expect it to change.
Jev with images
Jev 1.14 also reads images. Put the image in state as a chat-style image_url part with a base64 data URL, and refer to it by name in the questions. The key comes from a .env file:
# uv add requests opencv-python pydantic-settings
# .env: OPENROUTER_API_KEY=sk-or-v1-...
import base64

import cv2
import requests
from pydantic import SecretStr
from pydantic_settings import BaseSettings, SettingsConfigDict


class Settings(BaseSettings):
    model_config = SettingsConfigDict(env_file=".env", extra="ignore")

    openrouter_api_key: SecretStr
    openrouter_url: str = "https://openrouter.ai/api/alpha/decisions"
    jev_model: str = "typesafe/jev-1.14"


settings = Settings()
openrouter_api_key = settings.openrouter_api_key.get_secret_value()
Jev rejects images outside its limits instead of resizing them: PNG or JPEG, 280 to 1568 px per side, 16 MiB per file (full limits). So shrink the image first and encode it back to JPEG bytes. Encoding the cv2.imread array directly sends raw pixels, not a JPEG, and the request fails:
# 280px <= Dim <= 1568px

URL = "jev_ezio.png"

src = cv2.imread(URL, cv2.IMREAD_COLOR)  # BGR, no alpha, applies EXIF rotation
h, w = src.shape[:2]
scale = min(1, 1568 / max(h, w))  # only shrink
src = cv2.resize(
    src, (round(w * scale), round(h * scale)), interpolation=cv2.INTER_AREA
)

ok, jpg = cv2.imencode(
    ".jpg", src, [cv2.IMWRITE_JPEG_QUALITY, 90]
)  # pixels -> JPEG bytes

photo = {
    "type": "image_url",
    "image_url": {"url": "data:image/jpeg;base64," + base64.b64encode(jpg).decode()},
}
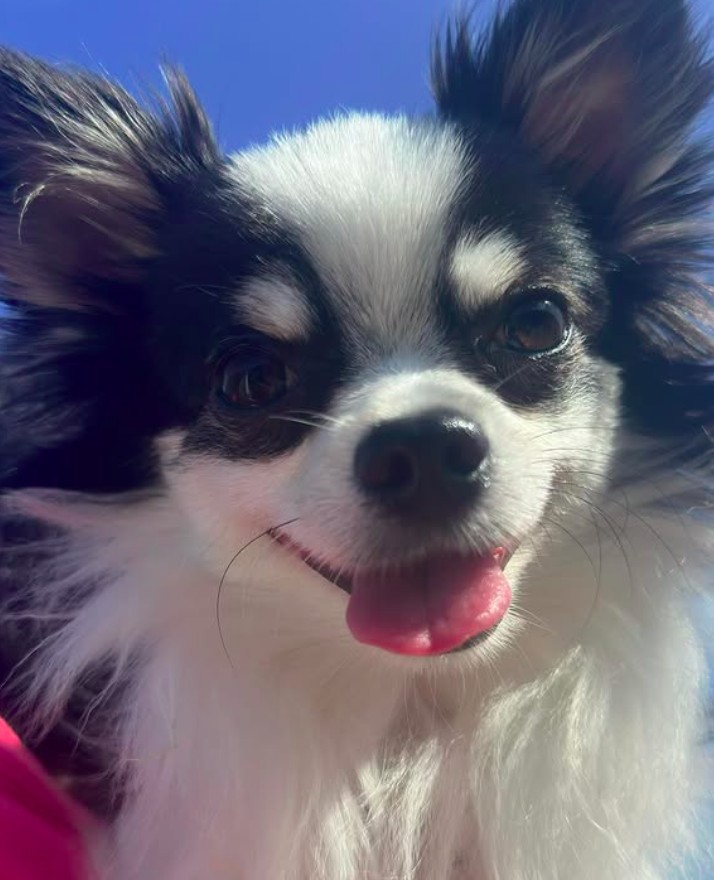
Three questions about the photo: is it safe for work, which animal is in it, and is it a real photo or artificial:
response = requests.post(
    settings.openrouter_url,
    headers={"Authorization": f"Bearer {openrouter_api_key}"},
    json={
        "model": settings.jev_model,
        "state": {"photo": photo},
        "questions": {
            "safe_for_work": {
                "type": "noul",
                "instructions": "Is `photo` safe for work?",
                "criteria": {
                    "true": "Fine to open at the office: no nudity, sexual content, gore, blood or graphic violence.",
                    "false": "Shows nudity, sexual content, gore, blood or graphic violence.",
                },
            },
            "animal": {
                "type": "choice",
                "instructions": "Which animal is in `photo`?",
                "criteria": {
                    "dog": "A dog.",
                    "cat": "A cat.",
                    "turtle": "A turtle or tortoise.",
                    "other_animal": "Some other animal.",
                    "no_animal": "No animal at all.",
                },
            },
            "style": {
                "type": "choice",
                "instructions": "Is `photo` a real photo or artificial?",
                "criteria": {
                    "real": "A photo of the real world taken with a camera.",
                    "artificial": "Drawn, painted, rendered or generated: anime, cartoon, illustration, 3D render or game art.",
                },
            },
        },
    },
)
if not response.ok:
    print(response.status_code, response.text)
response.json()["answers"]
{'safe_for_work': {'type': 'noul', 'noul': 0.98},
 'animal': {'type': 'choice',
  'choice': 'dog',
  'probabilities': {'dog': 1,
   'cat': 0,
   'turtle': 0,
   'other_animal': 0,
   'no_animal': 0},
  'confidence': 1},
 'style': {'type': 'choice',
  'choice': 'real',
  'probabilities': {'real': 0.92, 'artificial': 0.08},
  'confidence': 0.84}}
The no_animal option is there because a choice always picks one of its options; without it, a photo with no animal would be forced into the closest one. The safe_for_work answer is a probability, so you pick the threshold, for example accept only above 0.9.
Cheaper Inference does not offer Jev in either form.